Data Lineage Diagrams
A Data Lineage diagram answers a question every architect gets asked and few models can answer: where did this data actually come from, and who else is using it?
Pick any part of the solution that touches data — an application, a service, an API, a report — and ArchRepo traces the data backwards to its origin and forwards to everyone who consumes it, one piece of data at a time.
What the Diagram Shows
The item you chose sits in the middle. Everything to its left is upstream — the chain of things that produced the data it reads. Everything to its right is downstream — everything that goes on to use the data it writes.
The diagram above is a simplified concept. Here is a real one, traced live from a project’s model — RetailMax’s Fulfilment Feed, showing the full journey from catalogue to despatch reporting:
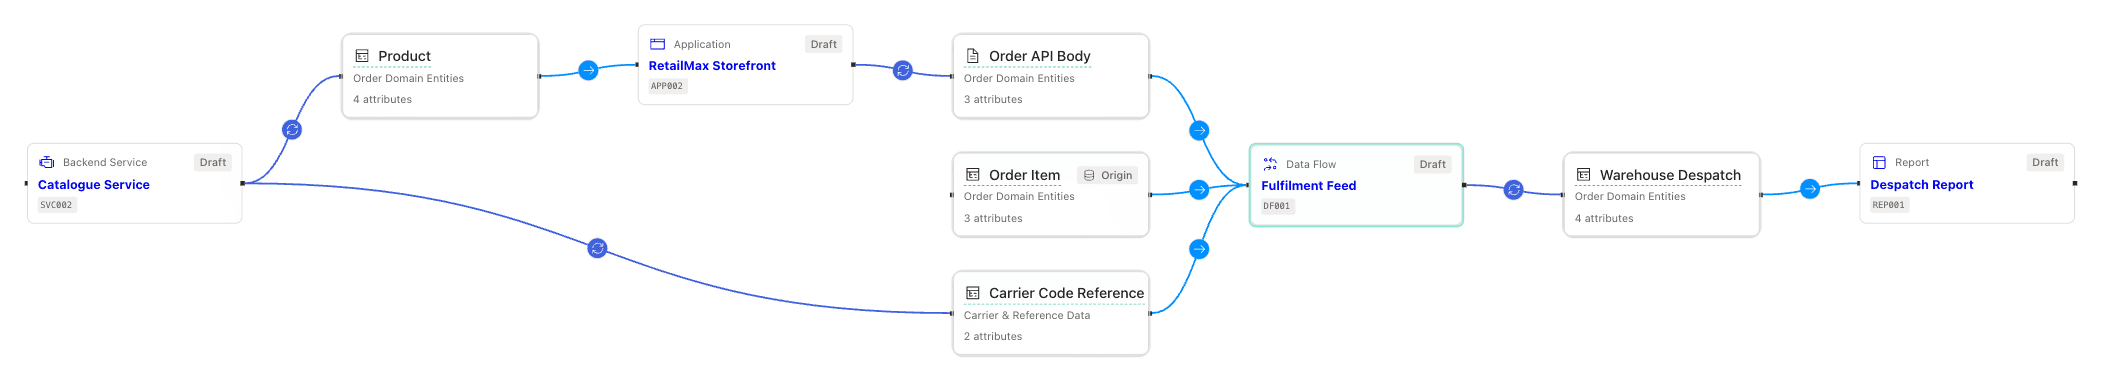
The chain alternates between two kinds of box:
- Specifications — the applications, services, APIs, data flows, reports, UI components and data migrations that do something with the data. Each shows its type, its reference and its status.
- Data entities — the individual table, message, document or record structure being passed along, with the Data Set it belongs to and how many attributes it has.
Every connection is labelled with what that specification does to that entity:
| Connection | Meaning |
|---|---|
| Reads | The specification consumes the entity but never changes it. |
| Writes | The specification produces the entity. |
| Modifies | The specification changes an entity that already exists. |
This is entity-level lineage, not data set-level. Knowing that two systems both touch the “Customer Master” data set tells you almost nothing. Knowing that the Address record inside it is written by the CRM Sync Service and read by three downstream reports is an answer you can act on. That precision is the whole point of the diagram — and it depends on the modelling described in Getting Data onto the Diagram below.
Badges on the Boxes
| Badge | Meaning |
|---|---|
| Origin | Nothing further upstream — this is where the data enters the solution. |
| Imprecise | The trace could only get as far as the Data Set. This item is linked to a whole Data Set — by a read or write relationship — but has no Data Use & Mapping rows for that Data Set at all, so there was nothing more precise to follow. A prompt to go and tighten the model. |
| +N alternates | Several items were modelling the same real hop, so they have been merged into one box to keep the picture readable. |
Controls
- Item selector — on the project Diagrams tab, choose which item to trace from. Items are grouped by type, then by category.
- Entity filter — an item usually touches several entities at once, which makes a busy picture. Narrow the diagram to a single entity to follow one thread cleanly.
- Expand carriers — by default ArchRepo hides pass-through transport hops (a data flow or stream that simply carries data without changing it) so the picture shows the things that actually act on the data. Turn this on to see the literal transport path. It is greyed out when there is nothing hidden.
- Download — saves the current view as an image.
Why It Is Useful
Answering “where does this field come from?” in seconds. This is normally an archaeology exercise across spreadsheets, source code and whoever has been there longest. If the model is populated, the answer is a diagram.
Impact analysis before you change anything. Before you retire a service, change a message format or add a column, the downstream half of the diagram tells you exactly who is going to feel it. That list is difficult to be confident about any other way, and expensive to get wrong.
Faster incident and data-quality triage. When a number on a report is wrong, the upstream chain is the shortlist of places the fault can be. You work back along the chain rather than guessing.
Evidence for governance and compliance. Data protection, financial and regulatory reviews all ask for provenance: where personal or regulated data originates, what transforms it, and where it ends up. The diagram is that evidence, derived from the design rather than written up separately after the fact.
Finding the gaps in your own design. An Imprecise badge means an item is linked to a whole Data Set but has no Data Use & Mapping rows for it, so nobody has said which entities inside it that item actually touches. An entity with no writer upstream means nothing in the design produces the data something else depends on. Lineage exposes both, and both are cheaper to fix at design time.
The trace is worked out from your model every time you open it — it is never a stored copy that can drift. Correct the model and the lineage is correct immediately.
Getting Data onto the Diagram
The diagram can only show what the model has been told. Lineage is built from the data uses recorded on your specifications — nothing is inferred from names, and a plain relationship between two items is not enough on its own.
There are three steps.
1. Model the entities inside your Data Sets
Lineage connects specifications through entities, so the entities have to exist first. In each Data Set, use the built-in data modeller to define the entities — tables, JSON structures, message payloads, file layouts — that the data set contains.
A Data Set with no entities modelled can never carry a lineage chain.
2. Record what each specification reads and writes
On any specification that touches data, open the Data Use & Mapping section and choose New Data Usage. You will be asked:
- Does this item just read the data, or can it modify the data? — Read-Only or Updates Data. This is what puts the arrow labels on the diagram, and it decides which side of the chain the item lands on.
- Which Data Set is the data entity in?
- Which data entity does it read or update? — this is the step that matters most, and the row cannot be saved without it. The chain joins up entity by entity, so this is the answer that connects your item to everything around it.
- An optional summary of how the data is used.
Repeat for every entity the specification touches. The chain joins up wherever one item writes an entity that another item reads.
The entity is what connects the chain — not the Data Set. Two items that both name the same Data Set but different entities are not connected, and two items that name the same entity are connected even if nothing else in the model links them. If a diagram looks emptier than you expect, the usual cause is two items naming the same Data Set but different entities — or an item that has only been linked to a Data Set, with no Data Use & Mapping rows recorded against it at all, which shows as Imprecise.
3. Record transformations where data is reshaped
Where a specification takes data in one shape and produces it in another, record a transformation rather than separate read and write rows. Choose New Transformation, give it a name — Order Flattening, Address Standardisation — and then list, in one place, every entity it touches:
| Role | Meaning |
|---|---|
| Sources | Entities the transformation reads from. |
| Targets | Entities the transformation writes to. |
| Reference data | Tables used along the way. |
Transformations are what let lineage cross a change of shape. Without them, the entity that comes out looks unrelated to the entities that went in, and the chain stops there.
You can go further and map individual attributes — which source field becomes which target field, and whether it is copied, transformed, looked up, split, merged or ignored. That detail drives the Data Mapping diagram; lineage itself only needs the entity-level Sources, Targets and Reference data.
Which Item Types Can Carry Data Uses
Only the specification types that genuinely act on data have a Data Use & Mapping section, and only those types get a Data Lineage tab:
APIs · Applications · Backend Services · Data Flows · Data Migrations · Reports · UI Components
Data Sets themselves are not on this list. A Data Set is the data being traced, not something that acts on it.
Where to Find It
Across the project — the project’s Diagrams tab, then Data Lineage in the switcher. Choose any eligible item to trace from. This is the view for open-ended exploration.
On a single item — the Data Lineage tab on any API, Application, Backend Service, Data Flow, Data Migration, Report or UI Component. It shows the same diagram already focused on the item you are looking at, so the answer sits next to the specification it is about.
When the Diagram Is Empty
| What you see | What it means |
|---|---|
| ”Choose an item above to see its data lineage” | No item selected yet on the project diagram. |
| ”This item has no traceable data lineage yet” | Nothing was found upstream or downstream. Either this item has no data uses recorded, or no other specification names the same entities. |
| ”No traced threads match the selected entity” | The entity filter is narrowed to something this trace does not include. Choose Show all threads. |
| ”This item cannot be traced…” | Shown on the project diagram when the item has no Data Use & Mapping rows to trace from. Record what it reads and writes, following the steps above. |